
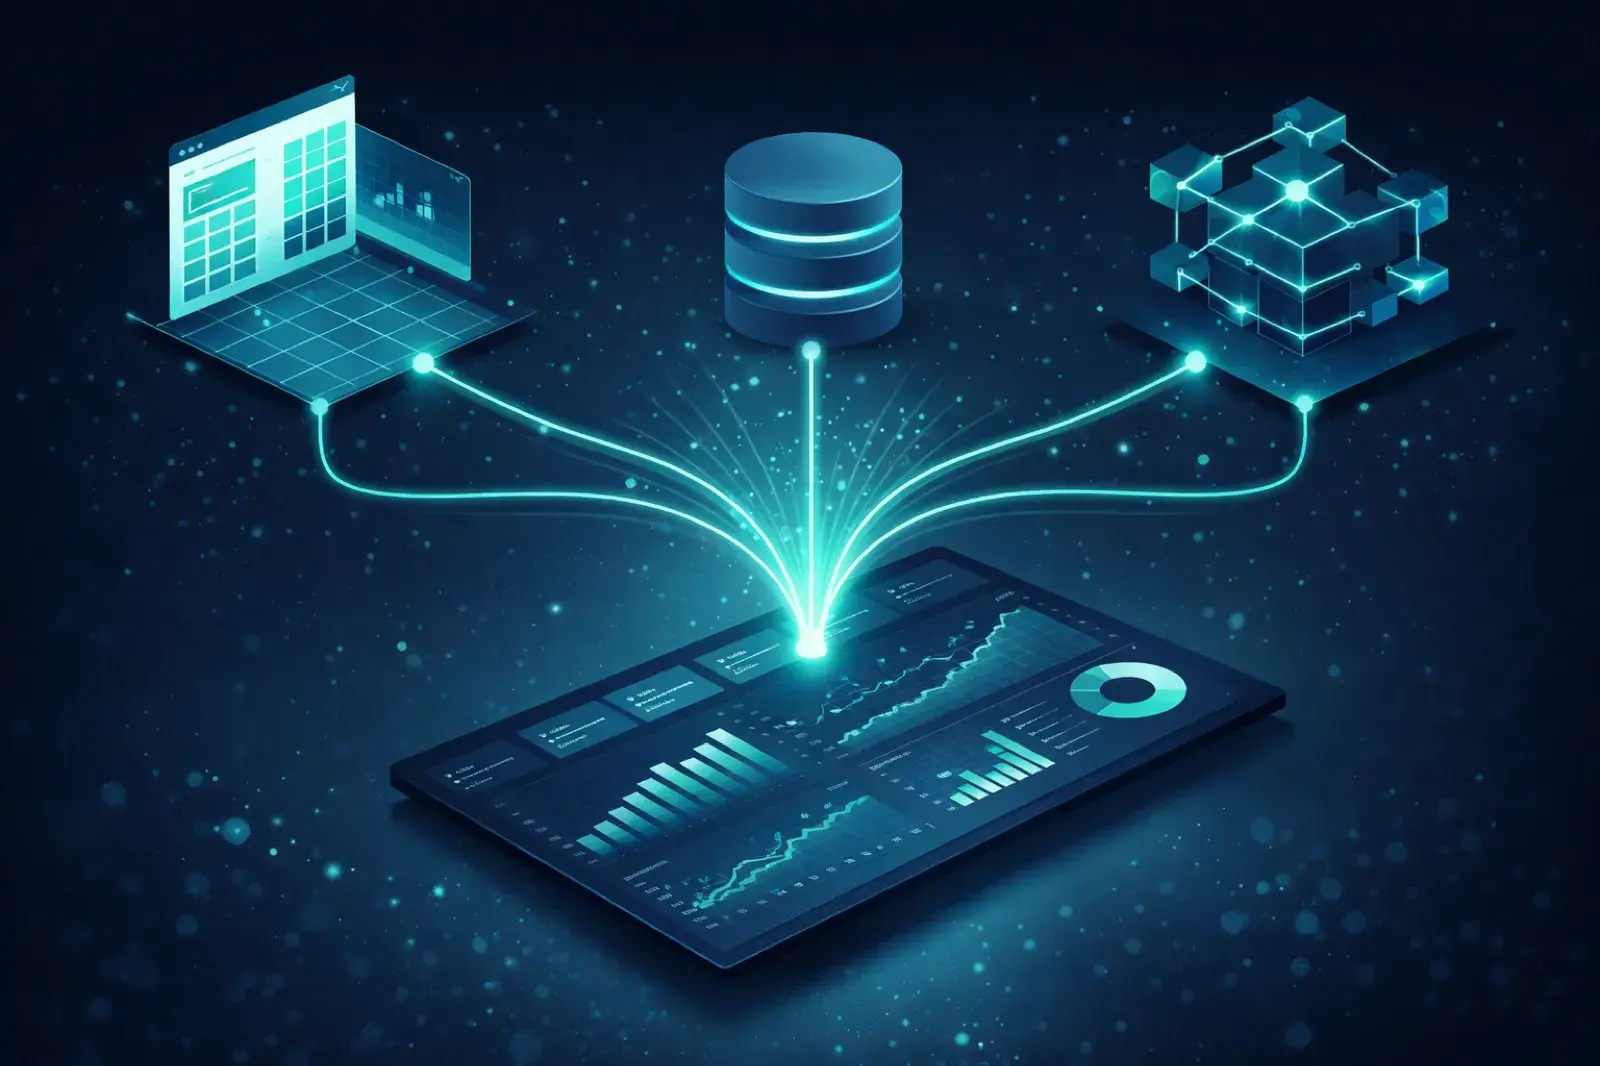
We build the pipelines and infrastructure that turn scattered, messy data into clean, reliable assets your team can actually use.
Most analytics projects fail before they start. Not because the models are wrong or the dashboards are ugly, but because the data feeding them is incomplete, inconsistent, or days out of date. If your team spends more time cleaning spreadsheets than analyzing trends, you have a data engineering problem.
We design and build the infrastructure that makes everything else possible: reliable pipelines, well-modeled warehouses, and automated quality checks that catch issues before they reach your reports. Whether you are starting from scratch or modernizing a legacy system, we build for where your business is headed, not just where it is today.
Every pipeline we build is documented, tested, and designed to be maintained by your team long after our engagement ends. We do not create vendor lock-in. We create capability.
Automated pipelines that extract data from every source you rely on, transform it into analysis-ready formats, and load it into your warehouse on schedule.
A well-modeled warehouse built for the queries your team actually runs, not a generic template that slows down as your data grows.
Purpose-built infrastructure on AWS, GCP, or Azure that scales with your business and keeps costs predictable.
Automated checks that catch bad data before it reaches your dashboards, with alerts that tell you exactly what broke and where.
Flexible storage for structured and unstructured data that supports both analytics and machine learning workloads.
Dimensional models and schemas that make your data intuitive to query and fast to join, even at scale.
Tested migrations from legacy systems to modern platforms, with validation at every step to protect your data and keep downtime low.
Workflow orchestration with tools like Airflow, Prefect, or dbt that keeps every pipeline running on time and in the right order.
You have data in Salesforce, Stripe, Google Sheets, and a dozen other tools. Your team copies and pastes between them weekly. You need a single source of truth.
You want dashboards, forecasts, or internal tools, but your data is too fragmented to support them. You need the foundation before you can build the house.
Your on-premise database or aging warehouse is slow, expensive, and holding your team back. You need a modern, cloud-native platform without the risk of a messy migration.
We map every data source, catalog existing schemas, and identify gaps, duplicates, and quality issues before writing a single line of code.
We design how your data is stored, how it flows between systems, and how updates are scheduled, all based on your actual use cases, not theoretical best practices.
Pipelines are built iteratively with automated tests and data quality checks at every stage. You see working data flowing within weeks, not months.
Every pipeline, model, and config is documented so your team can maintain, extend, and troubleshoot independently.
Our Figment Forge project shows how clean data engineering powers a retail analytics dashboard built on over $1M in anonymized sales data across 100K+ orders. Our LA 311 Dashboard demonstrates a full pipeline from public API to pre-computed aggregations, turning 369K+ raw service requests into an interactive analytics experience.
Book a free 30-minute scoping call. Bring the decision you need to support and a list of where the data lives, and we'll tell you honestly what it would take.
or email us directly at mazen@figmentanalytics.com